What actually happened
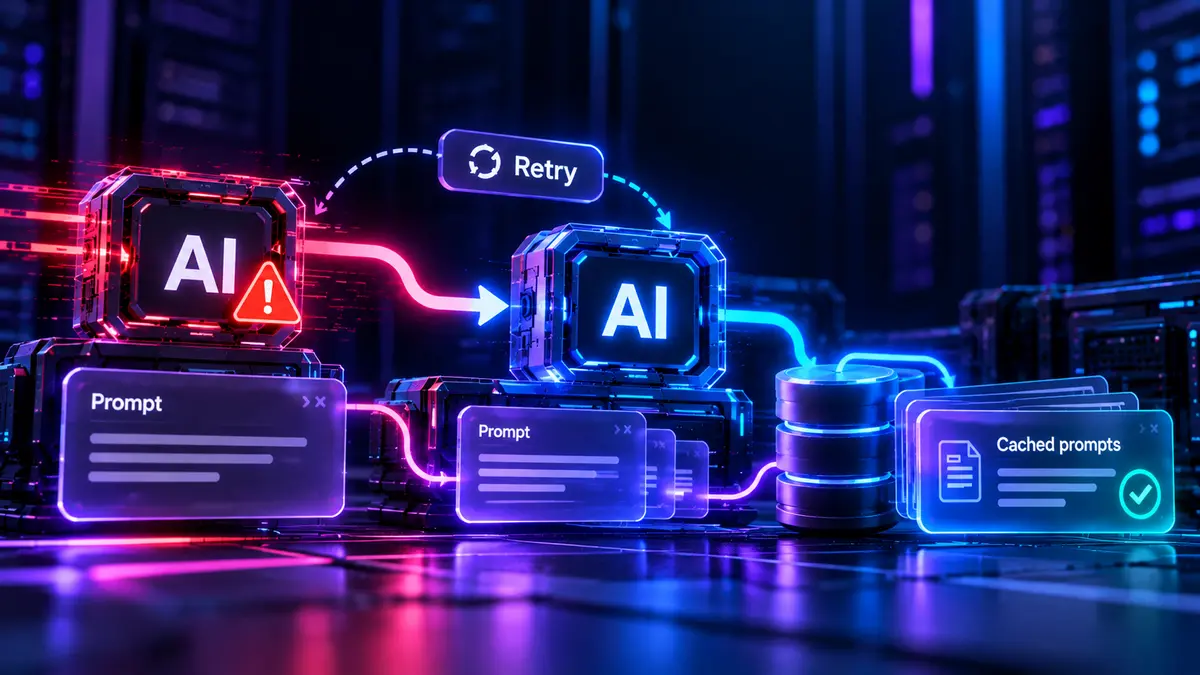
Make now lets an AI Agent use a second AI provider connection when its primary provider or model fails. The agent retries the run once using that fallback. Make's own AI Provider connection is the default fallback, and you can configure another connection. Both this setting and prompt caching are available in the Make AI Agent app on all plans.
The same update adds model-dependent prompt caching. With supported Claude models, Make exposes a cache-duration setting; providing a conversation ID also allows cached context to apply across repeated calls in that conversation. Supported OpenAI models reuse prompt content automatically. The repeated material can include system instructions and tool definitions, and Make describes lower latency and credit use as the intended benefit.
These are two separate controls with different outcomes. The fallback concerns availability when the model connection fails. Caching concerns repeated context processing. Neither makes an inaccurate model answer correct, and caching is not a blanket promise that every scenario will consume fewer credits.
Why a small team cares
Consider an online retailer using a Make agent to sort customer emails into shipping, returns and product questions. Its agent runs against the same store policies hundreds of times every week, then passes a draft reply to a staff member for approval. A provider outage during a busy period can leave requests stuck, while repeating a long policy prompt on each call creates avoidable processing.
A secondary provider connection gives this business another path when the first model cannot respond. Caching can make stable policy and tool context cheaper to reuse when the chosen model and conversation structure support it. For an operation with 2,000 monthly interactions, even small per-run improvements might matter, but the actual savings depend on prompt composition, cache hits, pricing and Make's credit calculation.
One practical requirement is easy to miss: two models do not necessarily return identical structured outputs. If downstream modules expect a specific JSON shape, the fallback must be tested against the same validation. A recovered model call that breaks the next scenario step is not a recovered business process.
Hype vs useful
This is worth adopting for existing Make users because provider failure is an ordinary operational problem. The announcement does not promise unlimited retries: Make attempts the fallback once. It also does not protect against API permission failures, invalid mappings, bad source data or outages affecting both providers.
Prompt caching should be measured using repeated runs with stable context. A business that injects a different large instruction block into every request may see little benefit, while one reusing the same rules and tools is a better fit. Monitor completed jobs, failures, time per request and billed credits before claiming a saving.
There is no reason to rebuild a functioning n8n stack around this announcement. Comparable resilience can be engineered there with error handling and provider-routing logic. Make has made the common case easier to configure, which is useful for teams already paying for it.